
Executive Summary: The Hulu.com Node.js ETL (Extract, Transform, Load) project integrated Airtable, ElasticSearch, and Roadmunk directly with Jira. This automated data pipeline streamlined cross-platform synchronization, ensuring real-time consistency across project management tools and improving engineering team productivity.
Introduction to the Hulu ETL Architecture
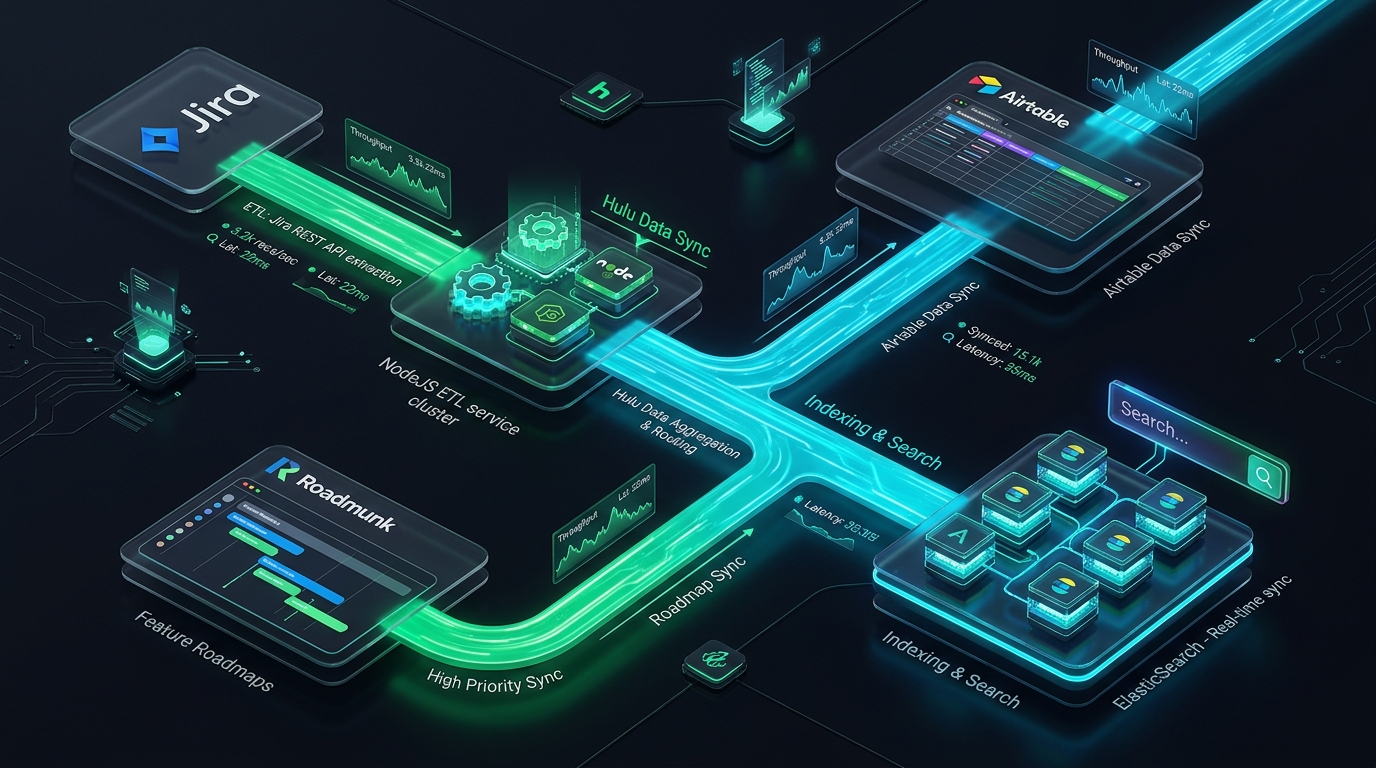
In the fast-paced environment of digital streaming services like Hulu, managing project data across disparate platforms requires deterministic automation. This engineering case study explores the development of a custom Node.js-based ETL pipeline designed to centralize and synchronize data between Airtable, ElasticSearch, Roadmunk, and Jira. By leveraging the asynchronous capabilities of Node.js, we built a scalable architecture capable of processing thousands of records without blocking the main event loop.
The primary goal was to eliminate manual data entry, reduce human error, and provide product managers and engineering leads with a unified, real-time view of project statuses, roadmaps, and sprint capacities.
Core Technologies and Platform Integrations
| Platform | Architectural Role | Synchronization Direction & Protocol |
|---|---|---|
| Node.js + Redis | Non-blocking orchestration & rate-limit queue | Async REST workers with exponential backoff |
| Jira REST API | Authoritative system of record for epics/stories | Bidirectional webhook & batch delta polling |
| Airtable | Flexible operational intake & spreadsheet views | Inbound field extraction mapped to Jira custom fields |
| ElasticSearch | Real-time full-text search & executive analytics | Bulk document indexing on every state transition |
| Roadmunk | Executive timeline & strategic roadmap alignment | Automated milestone updates upon Jira epic completion |
Node.js as the Orchestration Engine
Node.js was selected as the primary backend runtime for this ETL pipeline due to its non-blocking I/O model and mature API client ecosystem. Node.js allowed us to orchestrate concurrent HTTP requests across third-party APIs, normalize payloads against a canonical schema, and dispatch bulk index writes:
export interface JiraEpicRecord {
  key: string;
  summary: string;
  status: 'To Do' | 'In Progress' | 'Done';
  sprintPoints: number;
  updatedAt: string;
}

export async function syncEpicToDownstream(
  epic: JiraEpicRecord,
  elasticClient: { index: (doc: unknown) => Promise<void> },
  roadmunkClient: { updateMilestone: (key: string, status: string) => Promise<void> }
): Promise<void> {
  const normalizedDoc = {
    epicKey: epic.key,
    title: epic.summary.trim(),
    workflowStatus: epic.status,
    storyPoints: epic.sprintPoints,
    syncedAt: new Date().toISOString()
  };

  await Promise.all([
    elasticClient.index(normalizedDoc),
    roadmunkClient.updateMilestone(epic.key, epic.status)
  ]);
}
Jira: The Central Source of Truth
Jira served as the foundational issue tracking and project management system. Our ETL pipeline interacted with the Jira REST API to extract ticket details, update custom fields, and transition issue states based on external triggers. Maintaining Jira as the central source of truth ensured that developers could continue working in their preferred environment without context switching.
Airtable, ElasticSearch, and Roadmunk Synchronization
Operational teams used Airtable for flexible intake, which our pipeline mapped directly to Jira epics. As records flowed through the transformation stage, normalized documents were indexed into ElasticSearch clusters for millisecond dashboard queries and pushed to Roadmunk so executive roadmaps reflected live engineering sprint progress.
Implementation Challenges and Solutions
Handling API Rate Limits with Redis
Navigating disparate rate limits across Airtable, Jira, and Roadmunk required a Redis-backed token-bucket queue. Outgoing requests were throttled per provider with jittered exponential backoff on HTTP 429 Too Many Requests responses, guaranteeing zero dropped updates during peak sprint transitions.
Schema Validation and Security
All API communications authenticated via OAuth 2.0 and encrypted tokens over TLS 1.3. Payloads were validated against strict JSON schemas before loading; malformed records were quarantined and routed to Slack and PagerDuty alerts before they could pollute downstream indices.
Frequently Asked Questions
Why choose Node.js for an enterprise ETL pipeline?
Node.js excels at network I/O-bound workloads such as multi-API orchestration. Its event-driven architecture handles concurrent REST and webhook streams with minimal memory overhead.
How does automated Jira synchronization improve engineering velocity?
By automatically synchronizing state between Jira, Airtable, ElasticSearch, and Roadmunk, engineering and product teams eliminate manual status copying and operate from a single real-time data source.